
iterion dispatch — long-running dispatcher
The dispatcher turns iterion from a one-shot iterion run into a dispatcher: it polls an issue tracker, picks the next eligible issue, runs a workflow against it, and repeats — with retry, stall detection, per-state concurrency caps and hooks. It is the layer that makes "an AI sweeps the backlog" a real, supervisable thing rather than a cron + a prayer.
If you only want a kanban board with no autonomous loop, you don't need the dispatcher — see docs/native-tracker.md for the standalone tracker.
Quick start (zero config)
The fastest path is no YAML at all:
iterion dispatchCalled without an argument, the dispatcher boots with a built-in preset: the native kanban tracker, the studio HTTP surface on http://localhost:4892, polling every 30 s, and an embedded bot catalogue containing the nine default bots from bots/ as assignees. Out of the box you can:
- Open
http://localhost:4892/boardand create a ticket. - Set the ticket's assignee to one of the names below, drop it into a state marked
eligible(default:ready/in_progress), and the dispatcher picks it up at the next poll. - The studio's
/dispatcherroute shows the run in flight.
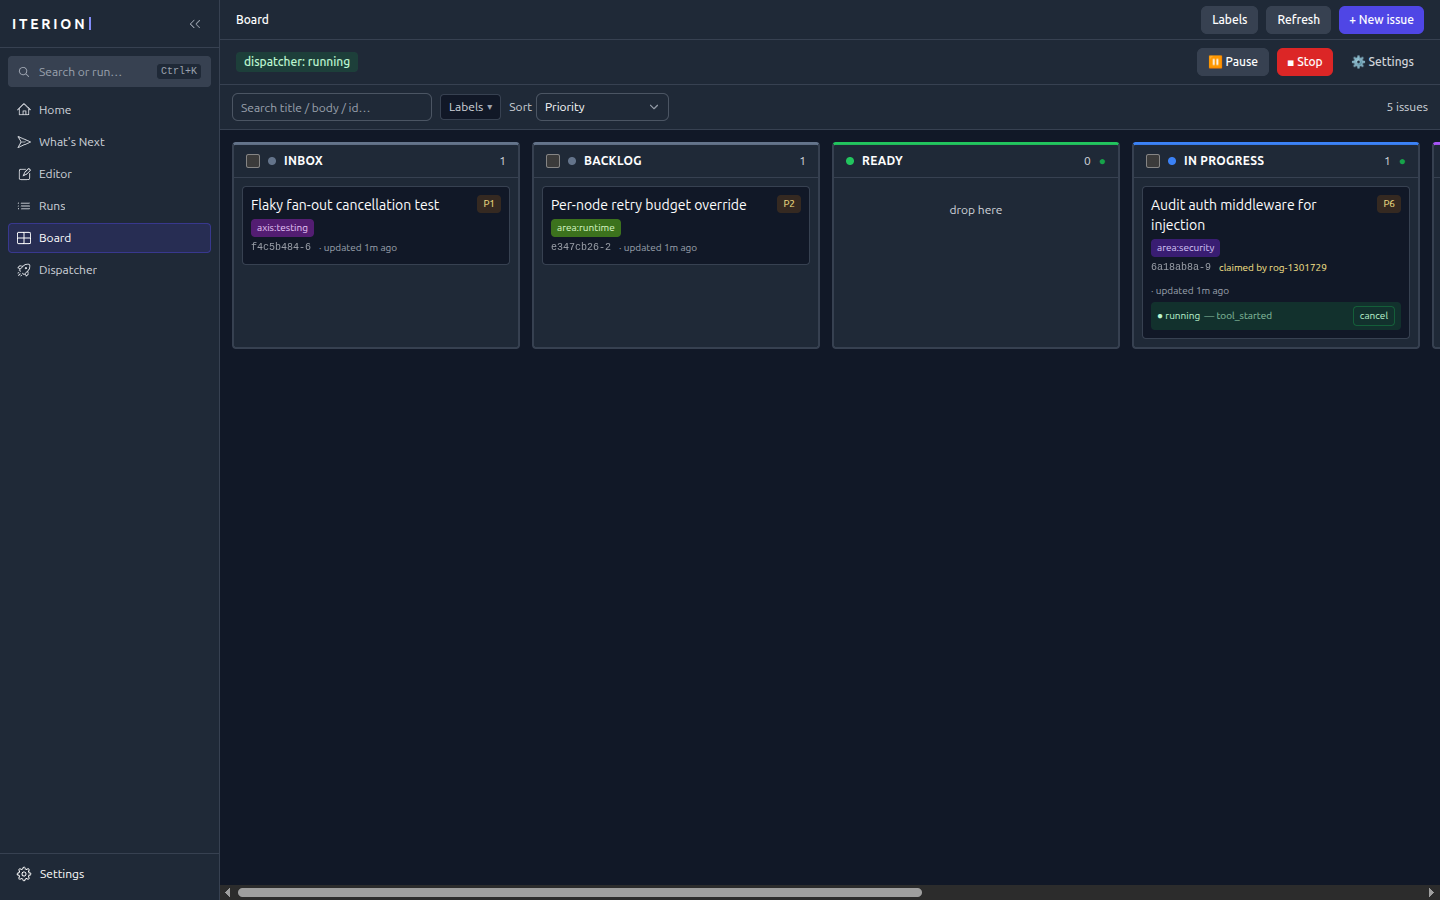
Once claimed, the ticket moves to in_progress and its run attaches to the card — a live status chip shows it executing right on the board:
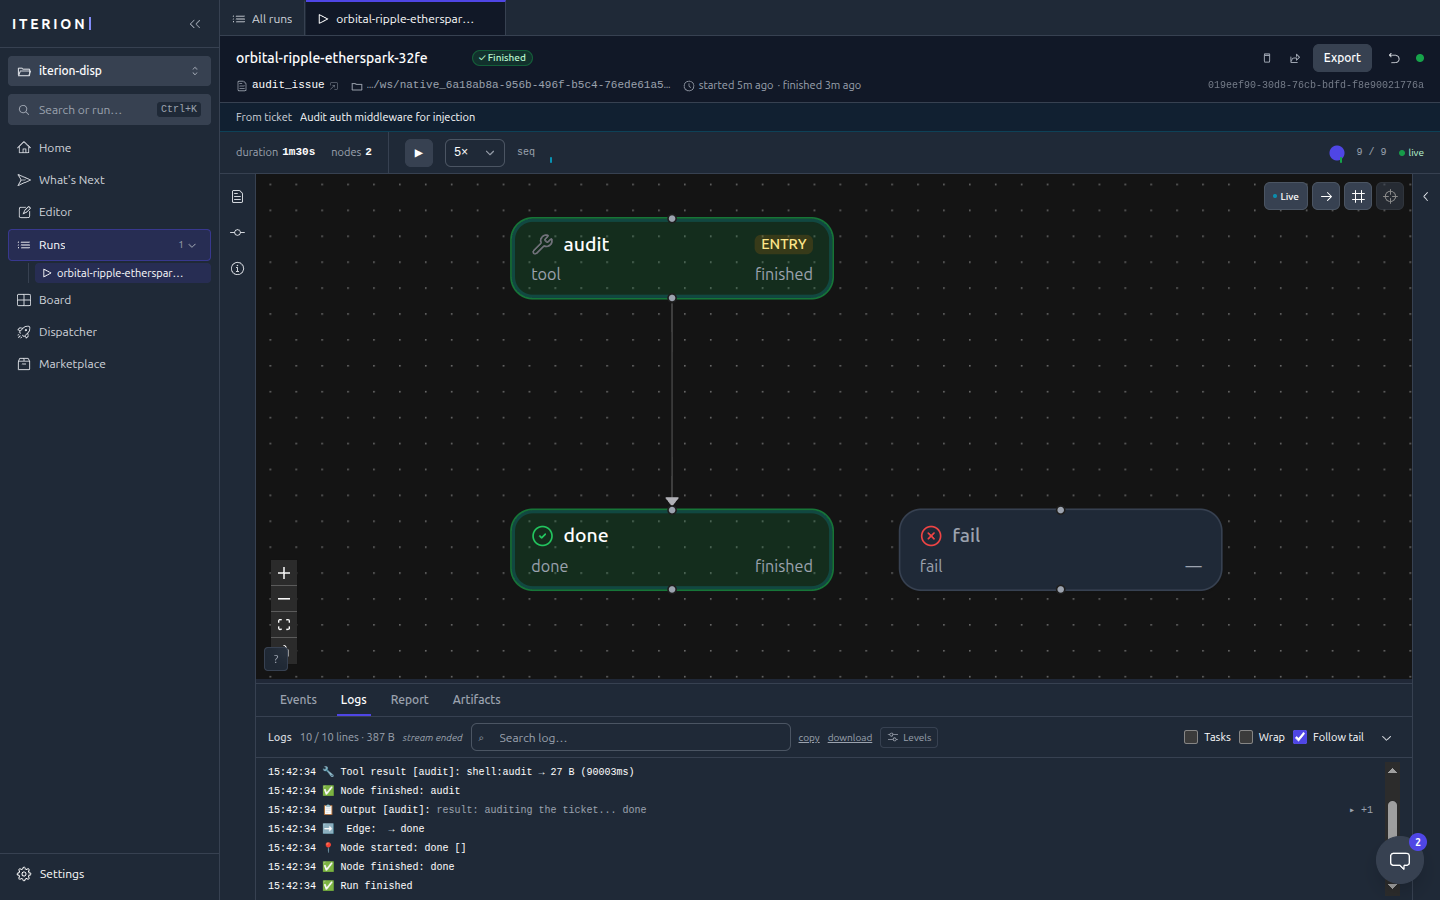
Open that run and the console records the ticket it came from (the From ticket header), closing the loop from issue to execution:
Built-in assignees (source bots):
| Persona | Assignee | Backing bot | What it does |
|---|---|---|---|
| 🛠️ Featurly | feature-dev | bots/feature-dev/ | One adaptive feature campaign with verified commits and deterministic build/test gates |
| 🌍 Willy | whole-improve-loop | bots/whole-improve-loop/ | Whole-codebase campaign applying one improvement axis site by site |
| 🌿 Billy | branch-improve-loop | bots/branch-improve-loop/ | Branch-diff review/improvement campaign with verified in-stride commits |
| 🧭 Nexie | whats-next | bots/whats-next/ | Conversational co-CTO for recommendation, board curation, roadmap study, and dispatch |
| 📚 Doki | docs-refresh | bots/docs-refresh/ | Doc-only alignment campaign over a deterministic footprint and advisory drift hints |
| 🔎 Revi | review-pr | bots/review-pr/ | Read-only review with one model family by default and optional cross-family dual mode; publishes findings to the board |
| 🛡️ Seki | sec-audit-source | bots/sec-audit-source/ | Source-code security audit (gitleaks/trivy/semgrep/gosec) |
| 📦 Depsy | sec-audit-deps | bots/sec-audit-deps/ | Supply-chain dep audit + LLM review |
| ⬆️ Renovacy | secured-renovacy | bots/secured-renovacy/ | Security-aware dependency upgrades with cumulative review |
| — | (unassigned) | default/ (embedded) | Generic triage agent: classifies the issue and recommends a next step |
Each assignee's input contract ({{issue.title}} + {{issue.body}} → the bot's main prompt var) is wired in pkg/cli/dispatch_defaults.go. Bots are extracted on first run under <store-dir>/dispatcher/bots/<name>/ (write-if-absent so local edits survive subsequent starts). Override the port via --port, the store location via --store-dir, or write a full YAML when you outgrow the defaults.
TL;DR — explicit YAML
# 1. Init the kanban + create a first issue.
iterion issue board init
iterion issue create --title "Investigate flaky test" --state ready --priority 5

# 2. Write an `iterion.dispatcher.yaml` next to your workflow.
cat > iterion.dispatcher.yaml <<'EOF'
name: dev-loop
workflow: ./workflow.bot
tracker:
  kind: native
dispatch:
  vars:
    user_prompt: "Issue {{issue.identifier}}: {{issue.title}}\n\n{{issue.body}}"
polling:
  interval_ms: 15000
agent:
  max_concurrent: 2
workspace:
  root: ./workspaces
server:
  port: 4892
EOF

# 3. Start the daemon. The dashboard lives at http://localhost:4892.
iterion dispatch iterion.dispatcher.yaml
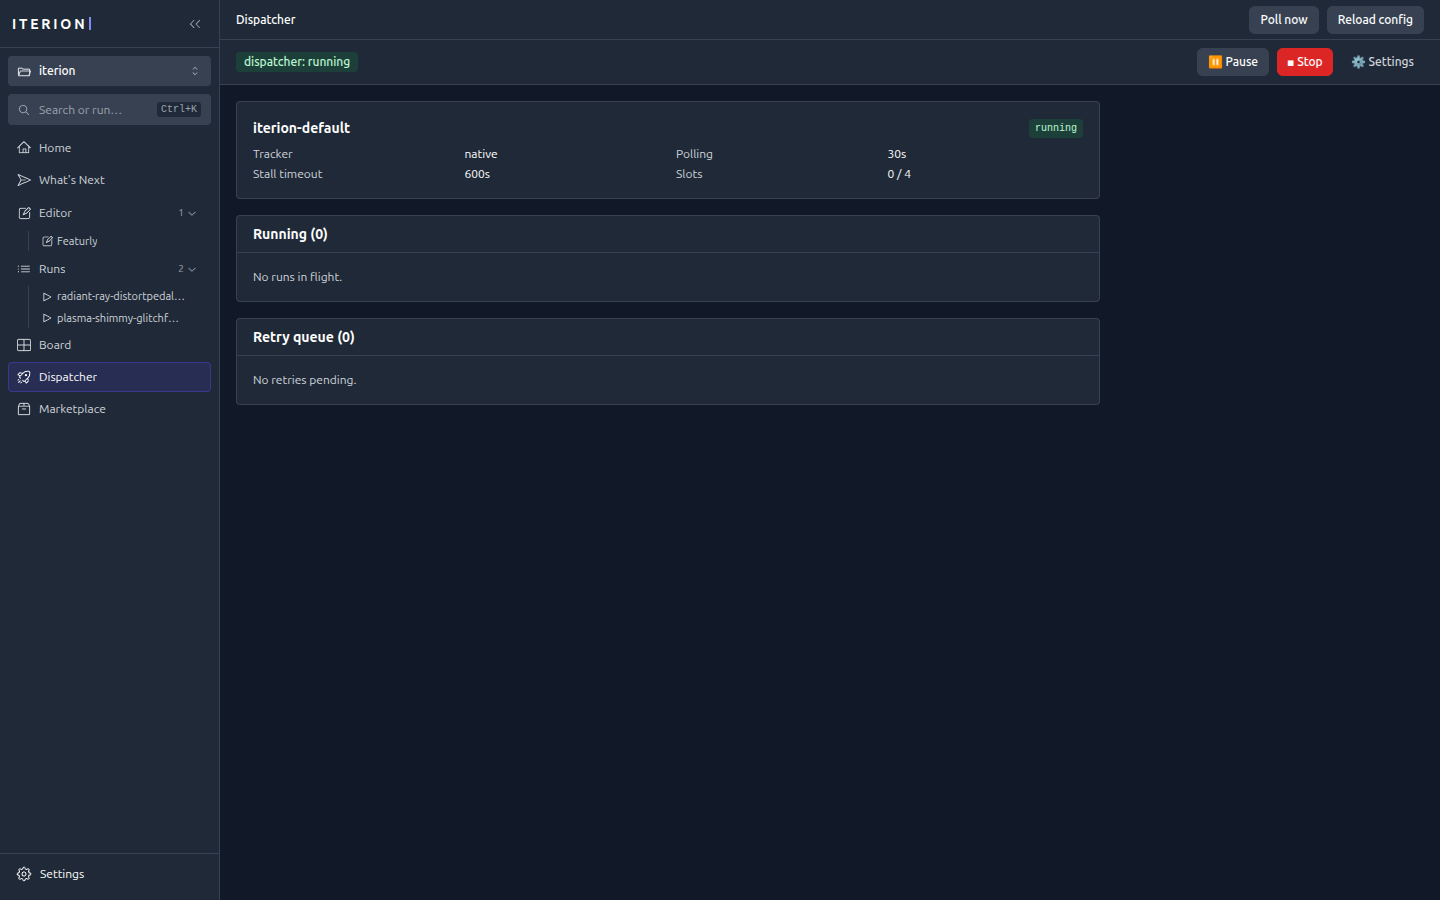
The studio's /dispatcher route renders the same daemon — its config, the in-flight runs, and the retry queue, with pause/stop controls:
Mental model
A single goroutine — the actor — owns all mutable state. Outside callers (HTTP handlers, retry timers, the config watcher, dispatch goroutines reporting completion) send typed messages on a buffered channel. This mirrors Symphony's GenServer design with fewer moving parts and zero shared locks across blocking tracker I/O.
State machine
Issues flow through:
The slot accounting is global (agent.max_concurrent) plus per-state (agent.max_concurrent_by_state). A workflow state in the per-state map cannot exceed its individual cap even when the global cap has room.
Paused runs — the awaiting_input column + parked sweep
A run that suspends for input (a human node → paused_waiting_human, or an operator soft-pause → paused_operator) is not a failure and is never retried. The dispatcher parks the card instead:
- the card moves into the dedicated
awaiting_inputcolumn (part of the default board; olderboard.json/ Mongo board configs are schema-upgraded automatically — the state is inserted right afterin_progress; fully-custom boards withoutin_progressare left untouched and the card simply stays in place), - the claim is retained (so no tick re-dispatches it), the slot is freed, and the denormalized ⏸ badge (
awaiting_inputon the issue) is set — the studio board shows "this pipeline needs me" at the column level and the card's answer form keys offlast_run_id.
Answering happens outside the dispatcher (answer-from-board, the run console, or iterion resume), so a per-tick parked sweep (reconcileParked) watches the parked cards' runs and finishes the lifecycle: run finished → agent.completed_state, hard failed → agent.failed_state (claim released, badge cleared). Resumable statuses (paused_*, failed_resumable, cancelled) keep the card parked — it genuinely still awaits the operator. The cloud board coordinator runs the same sweep for cloud-launched cards.
A reboot (new PID) drops the park-claim. in_progress stays eligible for crash-recovery, but a live last_run is never replaced by a sibling planner from the workflow entry:
last_run status | On the next tick / boot |
|---|---|
paused_waiting_human / paused_operator | Re-park: awaiting_input, same last_run, no auto-resume (no answers). Only dispatcher-owned runs move the card — a pipelines-launched paused run keeps its card in place for the admission sweep, and still blocks any fresh mint. |
running | Hold while the owner process lives (run lock held). A dead owner (SIGKILL, host crash — lock free, past the 2-minute grace window) is promoted by the dispatcher itself: checkpoint → failed_resumable (then resumed), none → failed (a fresh run becomes legitimate). This works in --no-server deployments too, which have no runview orphan reaper. |
queued | Hold without probing the run lock. Pipeline-queued runs deliberately have no lock owner until a concurrency slot opens; their queue owner advances their state machine. |
failed_resumable | Resume the same run id. Internal stops (stall reap, external state change, daemon shutdown) cancel the run context with runtime.ErrRunInterrupted as the cause, so the engine persists this status — which is what keeps stall/shutdown recovery automatic. |
cancelled | Hold, never auto-resume: only an operator produces this status now, and resuming it would undo their decision. The card is held before the claim with a visible reason; the way out is an explicit resume, or dropping the pointer (⋯ → Retry from zero on the pipeline board, iterion issue update --clear-last-run from a terminal). |
finished | No hold: a fresh run is allowed — dragging the card back to an eligible column is the re-queue gesture. |
none, or hard failed, and the ticket is explicitly eligible | The only other legitimate fresh run. |
The stranded-pause sweep (reconcileStrandedPaused) also runs while the dispatcher is paused, so a studio restart with desired: paused re-parks without dispatching. An out-of-band iterion resume --force that re-pauses on a later human node is picked up by the same sweep — the dispatcher worker already returned when the run first parked, so finishRun is not in the loop.
To really start over: drag a finished or hard-failed ticket back to ready. A failed_resumable one is not enough — the table above resumes it, so the board's Retry means resume on a dispatcher-owned board even though the studio's own admission loop would have minted a fresh run. Drop the pointer to make the restart deterministic: ⋯ → Retry from zero on the pipeline board, or iterion issue update --clear-last-run. Same for a cancelled last_run, which holds the ticket (no fresh sibling) but is never auto-resumed — resume it explicitly, or drop the pointer.
In-progress transition (agent.running_state)
After tracker.Claim succeeds, the dispatcher transitions the issue to agent.running_state (default in_progress) so the kanban shows which tickets are being worked on right now. Behaviour:
| Event | Action |
|---|---|
| Claim succeeds, source ≠ target | UpdateState(id, running_state), record source |
| Claim succeeds, source == target | No-op (idempotent) |
| Claim succeeds, transition rejected | Log warn, continue (the claim is already taken) |
running_state: none (or YAML empty) | Transition disabled — issues stay in their source |
| Workspace create / runID mint fails | Revert state, release claim |
Run cancelled (context.Canceled) | Revert state, release claim, keep workspace |
| Run failed (non-cancel) | Revert state, release claim, schedule retry |
Run finished cleanly (err == nil) | No revert. If the workflow moved the state itself (docs-refresh → review), that is honoured. If it left the card in running_state, the dispatcher moves it to agent.completed_state (default review) — see maybeTransitionToCompleted. |
| Daemon shutdown (Ctrl+C, SIGTERM) | Revert each in-flight ticket's transition |
Every revert is best-effort and protected by a RefreshStates safety check: the dispatcher only flips the state back when the issue is still in running_state. If the workflow already moved it forward (e.g. docs-refresh → review) or the operator dragged the card on the kanban mid-run, the revert is skipped so the operator's action isn't clobbered.
To disable the transition (e.g. boards without an in_progress column), set agent.running_state: none:
agent:
  max_concurrent: 2
  running_state: none   # keep claimed issues in their source state
External trackers (GitHub, Forgejo) map the abstract state to labels; if the YAML's state_mapping doesn't declare in_progress, UpdateState returns ErrTransitionRejected and the dispatcher logs + continues without aborting the dispatch.
Polling tick
Each tick (polling.interval_ms, default 30s):
- Reconcile stalled. For every in-flight run, if
time.Since(LastEventAt) > stall.timeout_ms, cancel its context. The worker goroutine then returns and the actor schedules a retry. Setstall.timeout_ms: 0to disable. - Refresh tracker states. Ask the tracker for the current state of every running issue. If the state moved out of the eligible set (operator closed the GitHub issue, dragged the native card to "done"), cancel the worker. The dispatch is yielded back to the tracker as the source of truth.
- Fetch candidates.
tracker.ListCandidates(ctx). The native adapter filters byEligibleboard states; the GitHub adapter passes labels throughgh issue list --search. Every external adapter (github/forgejo/gitlab) also honors body-declared dependencies: an issue whose body opens a line withDepends on #N/Blocked by #Nis held out of the candidate set while#Nis still open (the native tracker has its own richer blocker model). Resolution is best-effort and fail-open — a blocker holds the issue only when#Nis positively seen open among the issues this poll fetched. Because that fetch is scoped by the configuredinclude_labels, a blocker sitting in a different label or state is not seen and fails open (the issue dispatches); likewise a typo, a closed issue, or a cross-repo ref never holds. So a mis-parse can only under-block, never silently wedge a ticket. Each hold is logged at info level. - Sort.
priority desc, created_at asc, identifier asc. - Dispatch. Walk candidates, skip those already claimed locally or queued for retry, and dispatch as long as both global and per-state slots have room.
- Broadcast snapshot. Publish to the WS bridge so the dashboard shows the new state.
Claim selection on the cloud board — what is never claimed
The cloud board dispatcher (one per server replica, over the Mongo board) has no configured default bot: a card is launchable only if it names a bot. Its candidate query therefore lists unclaimed cards in the launch column that carry a bot — the filter is in the query, not a skip after the listing, because the batch is capped and bot-less cards (never written, so always the oldest) would otherwise fill every batch and starve the launchable ones. A ready card with no bot is roadmap content, typically one a project-board sync moved there (the default map lands every Planned ticket in ready, see github-board-sync.md); it is neither claimed nor moved until something stamps a bot on it.
Before claiming a listed card, the tick runs the launch preconditions — a run service, a bot, a bot the resolver can find, reserved bot-args that parse — and skips a card that fails them in its column, without claiming it (the local dispatcher's resolveExplicitBot shape). The same preconditions guard the launch itself, so a card that changed between the listing and the launch is caught there too; nothing ran, so no verdict is written on it: the card is returned to the column it was taken from under the machine provenance unlaunchable (no subscription re-fires on the return, no external board reflects it), and the claim is freed. It is never parked blocked — that column is a verdict on the card's work, and reaching it here parked 36 roadmap tickets in one pass and pushed Blocked onto the operator's GitHub board. A run that started and failed keeps filing blocked: that is the run's verdict.
A launch the run service refuses is a third class — transient, and retried with a backoff. Every error out of runs.Launch means no run was started (a credential-sealing failure, a queue outage, the server draining, a bot that does not compile, an invalid spec), so the card is returned to its column under the machine provenance launch_refused and its launch-refusal ledger (launch_refusal on the card: attempts, last reason, last instant, not_before) is advanced. The dispatch listing skips a card until its not_before — 1m after the first refusal, then 2m, 4m, … capped at 30m — so a refused card costs one attempt per backoff, not one per 5s tick, and queues behind the cards not tried yet (its updated_at moves). The server draining consumes no attempt: another replica claims the card on its next tick.
PR context resolution before launch uses this same ledger when the forge cannot be reached or a publish grant is temporarily unavailable. A proven fork, withheld head repository, or grant belonging to another team remains a terminal refusal and launches nothing. A replica that drains during the PR lookup returns the never-launched card without advancing the ledger; draining after launch leaves the existing run in place.
The org launch gate is one of these refusals. The board launch passes the same admission as an HTTP launch — gateLaunch: suspend → concurrency → launch rate → monthly caps (quotas-and-limits.md) — under the board-dispatcher identity on the card's team, and is metered the same way (the monthly slot is handed back when the run service then refuses). A denial reads on the ledger as `launch gate: <rule>:
After ITERION_BOARD_LAUNCH_ATTEMPTS consecutive refusals (default 8, about an hour and a half of retries; an unparsable value keeps the default and is logged once at startup) the card is filed blocked under the descriptive provenance launch_given_up, with the last refusal on its ledger and a give-up stamp naming it — reflected onto a bound external board on purpose: a human has to decide now. A successful launch (any run stamped on the card) clears the ledger, and so does an operator's Reopen, so a card reopened after the cap starts its retries afresh. The pipeline board shows a card filed this way in its Needs attention lane — the give-up stamp carries launch: true, so it needs no run to be current, and a card nobody could launch is not filed among the done ones.
Each verdict is logged once per card and reason, and every watchdog pass logs one tally line — N refused at admission, M returned to their column after a claim, K launches refused by the run service, G filed blocked after the launch attempt cap — so the ongoing cost of a broken card stays visible after its first line.
Retry queue
| Trigger | Delay |
|---|---|
Runner returned nil | Released, no retry. |
| Runner returned error | min(10s × 2^(attempt-1), agent.max_retry_backoff_ms) |
| Stall timeout | Same exponential backoff |
| External state change | Same |
Hook failure (before_run) | Same |
Retries are timer-driven (time.AfterFunc per issue, no min-heap). The timer callback posts cmdRetryDue{issueID} on the actor channel and the next tick reconsiders the candidate (which may by then have moved out of the eligible set — fine, the dispatcher releases without re-dispatching).
Terminal-state keys
Three agent.* keys decide where a ticket lands, each with a none opt-out:
| Key | Default | When it applies |
|---|---|---|
completed_state | review | The run finished cleanly and the workflow left the card in running_state. |
merged_state | done | The run's branch is merged from the studio — the canonical lifecycle is review → merged → done. Without it, merged issues sit in completed_state forever and the operator closes each one by hand. |
failed_state | blocked | max_attempts was reached (below). |
A board that does not define the target state refuses the move; the failure is logged and non-fatal, so custom boards degrade rather than break, and no operator is forced to opt out explicitly.
Giving up (agent.max_attempts)
agent.max_attempts defaults to 10 — with the 5-minute backoff cap that is on the order of tens of minutes of retries, enough to ride out a transient provider outage. A negative value retries forever.
Once agent.max_attempts is reached the dispatcher gives up: it moves the issue to agent.failed_state (default blocked) and drops the retry, so a doomed ticket stops burning model spend. If the board cannot represent that state the move is refused and the unbounded retry is kept instead — a ticket is never frozen in place.
A successful give-up also stamps the issue (Issue.gave_up — the run, the state written, the attempt count — plus an issue_gave_up event). The stamp exists because the give-up's target and the board's own Close target are the same terminal state: without it, readers cannot tell a dispatcher that ran out of attempts from an operator who filed the ticket, and the /pipelines board buries the failure in Closed instead of raising it in Needs attention (native tracker). It is not stamped when the terminal move was refused — a give-up that fell back to retrying has not given up.
The stamp expires on its own and for good: it names a run and a state, and each store drops it on any write in a different state. Since a retry resumes the same run id, a merely-stale stamp would otherwise revive when a human filed the ticket back into that state. Closing a ticket that is already sitting in the give-up's state changes nothing, so the three close surfaces — the pipeline board's Close, iterion issue close, and the board tool close_issue — clear the stamp explicitly.
Workspace lifecycle
Workspaces live below <workspace.root>/.issue-workspaces-v2/<readable-slug>--<sha256>/. The digest is derived from the original issue ID, so IDs that sanitize to the same slug cannot collide. Ownership records live outside the checkout in the sibling .owners/ directory.
workspace.persist | Behaviour |
|---|---|
keep | Reuse one stable per-issue workspace; never delete. Default (the empty value). |
cleanup_on_done | Use a run-ID generation and delete it on a clean dispatch return (engine success). |
cleanup_on_terminal | v1: identical to cleanup_on_done (terminal-state branching is unimplemented). |
The persist policy is snapshotted when a dispatch starts. Reloading it affects new dispatches only; an in-flight run keeps the cleanup decision under which its workspace was allocated.
Failed / cancelled dispatches retain their workspace. A resumable retry keeps the same run ID and generation. A non-resumable retry starts a fresh generation; the failed generation remains available for operator recovery. Before successful cleanup, the ownership marker is atomically changed from active to retired; interrupted directory/marker deletion therefore cannot block a later run-ID generation. The legacy stable-workspace Workspaces.Remove API is idempotent: when both the target and its ownership marker are already absent, removal succeeds without requiring an observed retirement transition.
Directories created by older versions directly under <workspace.root>/<sanitized-issue-id>/ are deliberately not adopted or deleted: the old sanitizer was many-to-one, so ownership cannot be proven from the name. A resumable run with only such a legacy/unowned workspace is not restarted fresh — that would mint a sibling planner and replay the prefix. Dispatch is deferred (visible as a skip) and the old directory is left untouched for operator recovery. To reclaim legacy directories, first confirm that no active/resumable run still references them, then inspect and move or delete them manually; automatic cleanup would risk deleting a different issue's colliding legacy workspace. If neither a run-scoped nor stable workspace shape exists at all (for example, an ephemeral workspace root disappeared while the run store survived), there is no unowned path to protect and the run cannot be resumed: the dispatcher starts a fresh isolated generation instead. The resolver also refuses workspaces whose symlink resolution lands outside the configured root.
These dispatcher workspaces are distinct from the engine's per-run worktree: auto — the latter is the runtime's git-isolation mechanism and lives inside the dispatcher workspace. Both layers keep their independent lifetimes.
Hooks
hooks:
  after_create:                       # runs once, when the workspace dir
    script: |                         # is first created.
      git clone --depth 1 https://github.com/${ORG}/${REPO} .
    timeout_ms: 120000
  before_run:                         # runs before every dispatch.
    path: ./scripts/prepare.sh        # `path:` invokes a script; `script:`
    timeout_ms: 60000                 # inlines a shell snippet. Exactly
                                      # one of the two must be set.
  after_run: null                     # runs after every dispatch (success
                                      # or failure). Best-effort: failures
                                      # are logged, not surfaced.
  before_remove: null                 # runs just before the workspace dir
                                      # is removed (commit + push your work
                                      # here if you want to keep it).
Hooks execute via sh -lc with cwd=<workspace path>. The dispatcher exports five environment variables before invoking the hook:
| Var | Value |
|---|---|
ITERION_ISSUE_ID | full ID, e.g. native:<uuid> |
ITERION_ISSUE_IDENTIFIER | human-readable, e.g. repo#42 |
ITERION_ISSUE_STATE | current workflow state |
ITERION_RUN_ID | the engine run ID for this dispatch |
ITERION_WORKSPACE | absolute workspace path |
A failed after_create or before_run aborts the dispatch and feeds the retry queue; failed after_run / before_remove are logged at WARN. Legacy/custom before_remove hooks that already run git worktree remove --force remain compatible: the dispatcher's exact post-delete deregistration first lists registrations and becomes a no-op when the hook already removed that path.
Dispatch templates
The dispatch.vars block maps workflow input vars to per-issue values using the same {{namespace.path}} syntax the .bot DSL exposes — but with a narrower set of namespaces.
Attachments are not dispatchable. There is no
dispatch.attachmentssupport: workflow attachments are binary files (referenced as{{attachments.<name>.path}}), and the dispatcher has no way to turn a per-issue template string into an attachment's bytes. Declaringdispatch.attachments(orassignee_dispatch[].attachments) is a load-time error, not a silent no-op — pass per-issue context throughdispatch.varsor a ticket'sbot_argsinstead. See ADR-013.
| Reference | Resolves to |
|---|---|
{{issue.id}} | full tracker ID |
{{issue.identifier}} | human label |
{{issue.title}} | issue title |
{{issue.body}} | issue body |
{{issue.state}} (alias of workflow_state) | current state |
{{issue.priority}} | priority as integer |
{{issue.assignee}} | assignee login |
{{issue.labels}} | comma-joined label list |
{{issue.labels_list}} | bracketed [a,b] form |
{{issue.url}} | metadata URL (native: empty, GH/Forgejo: html_url) |
{{issue.created_at}} / updated_at | RFC3339 timestamp |
{{issue.fields.<name>}} | typed value of a custom field (native only) |
{{issue.metadata.<key>}} | adapter-specific metadata |
{{dispatcher.name}} | the name: from your config |
{{dispatcher.run_id}} | the dispatch's run ID |
{{dispatcher.workspace_path}} | absolute workspace path |
{{dispatcher.attempt}} | 0 on first try, N for the (N+1)th retry |
The set of references is closed at parse time: typos like {{issue.tilte}} fail config validation rather than silently rendering an empty string at dispatch.
Routing by issue assignee
By default the dispatcher dispatches a single workflow (workflow:) for every eligible issue. To dispatch different workflows for different assignees — without running multiple dispatcher instances — add an assignee_workflows: map:
name: dev-loop
tracker:
  kind: native

workflow: workflows/triage.bot                  # default fallback

assignee_workflows:
  feature_dev:        bots/feature-dev/main.bot
  whole_improve_loop: bots/whole-improve-loop/main.bot
  secured-renovacy:   bots/secured-renovacy/main.bot
Resolution rules at dispatch time:
- If
issue.Assigneeis non-empty AND present inassignee_workflows, the dispatcher uses the mapped workflow. - Otherwise (empty assignee, or assignee not in the map), it falls back to
workflow:.
Matching is exact and case-sensitive. There is no glob / regex / pattern syntax — keep the keys aligned with what the producer stamps into --assignee. For the native tracker, the iterion issue create --assignee <name> flag drops name straight into issue.assignee; GitHub and Forgejo adapters use the first assignee's login.
Each assignee_workflows workflow is pre-compiled at startup and reused across dispatches — the same lifecycle as the default workflow:. Path resolution is relative to the dispatcher config file (same convention as workflow:). Missing files fail iterion dispatch startup with a precise error.
This is what makes whats-next.bot's kanban output auto-pilot: the bot stamps each issue with --assignee feature_dev (or any catalogued bot), and the dispatcher — with the mapping above — dispatches the matching workflow without any operator intervention.
Per-ticket bot + args fields
In addition to the assignee-based mapping above, every native tracker issue carries two dedicated typed fields that are copied into the dispatch request:
| Field | Type | Current stock effect |
|---|---|---|
Bot | string (JSON bot) | When non-empty, becomes the dispatch routing key: buildSpec sets routeAssignee = iss.Bot (winning over the issue's own assignee) and carries it on the spec as DispatchSpec.Assignee — not a workflow path. RoutingRunner selects the precompiled per-bot EngineRunner (its ByAssignee map is keyed by bot/assignee name) and the matching assignee_dispatch var overrides from that key; the bot FILE itself is resolved + route-checked by the guard at the top of dispatch() (the issue is skipped with a warning if the bot can't be resolved or has no active route). Use assignee_workflows: for production workflow routing today. |
BotArgs | map[string]string (JSON bot_args) | Merged over the rendered dispatch.vars key-by-key at launch time. BotArgs wins on shared keys; keys absent from the workflow's vars: schema are passed through with a warn log (the engine surfaces its own diagnostic). |
Current stock workflow selection is performed by the runner built at iterion dispatch startup:
assignee_workflows[issue.assignee]→ a precompiled per-assigneeEngineRunnerselected byRoutingRunner.cfg.workflow→ the precompiled defaultEngineRunner.
buildSpec folds a per-ticket Bot into the routing key DispatchSpec.Assignee (it wins over the issue's own assignee); the RoutingRunner above then selects the matching precompiled EngineRunner by that key, exactly as it does for an assignee_workflows assignee. DispatchSpec carries no workflow path — each EngineRunner runs the IR it was constructed with, so to route a brand-new workflow per ticket you add it to assignee_workflows: (or supply a custom runner that keys off DispatchSpec.Assignee).
Vars: assignee_dispatch[issue.assignee].vars (or dispatch.vars as fallback) are rendered first, then BotArgs is merged on top. See pkg/dispatcher/loop.go (buildSpec, lines 276-296) for the merge, and pkg/dispatcher/routing_runner.go for the stock assignee workflow selection.
How to set bot / bot_args: iterion issue create exposes --bot <id> and repeatable --bot-arg key=value (the latter lands in BotArgs, merged over the rendered dispatch vars) — see native-tracker.md. The same fields are settable over REST (POST /api/v1/native/issues or PATCH /api/v1/native/issues/{id} with { "bot": "feature_dev", "bot_args": { "feature_prompt": "…" } }), via the board MCP set_bot, or in the studio Launch modal. Only iterion issue update still lacks dedicated flags — change routing on an existing card via REST PATCH, set_bot, or the studio. Operators can also route purely through assignee_workflows: + assignee_dispatch:.
Per-assignee dispatch overrides
Different bots expect different input vars: feature_dev wants feature_prompt, whole_improve_loop wants improvement_prompt, secured-renovacy wants user_prompt. The global dispatch.vars: binds a single template for every assignee, which doesn't fit a heterogeneous bot catalogue.
assignee_dispatch: solves that — when an issue's assignee has an entry here, its vars: replace the global dispatch.vars wholesale for that dispatch:
workflow: workflows/triage.bot
assignee_workflows:
  feature-dev:        bots/feature-dev/main.bot
  whole-improve-loop: bots/whole-improve-loop/main.bot
  secured-renovacy:   bots/secured-renovacy/main.bot

assignee_dispatch:
  feature-dev:
    vars:
      workspace_dir:  "{{ dispatcher.workspace_path }}"
      feature_prompt: "{{ issue.title }}\n\n{{ issue.body }}"
  whole-improve-loop:
    vars:
      workspace_dir:      "{{ dispatcher.workspace_path }}"
      improvement_prompt: "{{ issue.title }}\n\n{{ issue.body }}"
  secured-renovacy:
    vars:
      workspace_dir: "{{ dispatcher.workspace_path }}"
      user_prompt:   "{{ issue.title }}\n\n{{ issue.body }}"

dispatch:
  # Fallback for issues with no assignee or an unmapped one.
  vars:
    issue_title: "{{ issue.title }}"
    issue_body:  "{{ issue.body }}"
Validation rules:
- Every
assignee_dispatchkey must have a matchingassignee_workflowsentry — otherwise startup fails with a precise typo-catching error. - Templates are parsed at load time; an unknown
{{ issue.foo }}/{{ dispatcher.bar }}field fails fast.
The zero-config mode (iterion dispatch) uses exactly this mechanism to wire each embedded bot to the issue title/body — see pkg/cli/dispatch_defaults.go.
Deterministic ticket router (PR-aware)
Opt-in. When enabled, an unassigned new issue (no Bot, no Assignee) is routed BEFORE the normal resolution by whether a PR already links it:
- No linked PR → the issue routes to the implement bot (Featurly,
feature-devby default) and is stampedbot:featurly. Featurly implements it and opens a PR — which the inbound PR-webhook then picks up (Revi review, or Billy on a same-repo ticket PR — see webhooks.md). - A PR already links it → the dispatcher steps aside (records a dispatch-skip, stamps
bot:billyfor visibility) and does not launch anything. The PR-webhook owns that work: it runs the branch-improvement bot (Billy) on the PR branch. Dispatching Billy from the issue would be wrong — an issue carries no PR branch, so Billy would review an empty diff. This is the ticket↔PR dedup: Billy runs exactly once, on the PR, via the webhook.
ticket_router:
  enabled: true
  implement_bot: feature-dev   # bot for a PR-less issue (default)
GitHub setup note. GitHub's gh issue edit --add-label errors if the label doesn't already exist in the repo, so the visible bot:featurly / bot:billy labels (and the tracker's claimed_label) must be pre-created (gh label create bot:featurly …). The label apply is best-effort and never blocks the routing decision, but the claim (same --add-label seam) does — an issue can't be dispatched until its claimed_label exists. A GitHub issue also needs a state_mapping state to be a candidate at all (an unlabeled issue with no mapped state is skipped). The native tracker auto-manages its labels, so this only applies to the github/forgejo adapters.
The PR-existence check + the visible bot:* label are best-effort tracker capabilities (HasLinkedPR / ApplyLabel, type-asserted at runtime). The GitHub adapter implements both via the gh CLI; a tracker that can't answer "does this issue have a linked PR?" (native/forgejo today) degrades to routing every unassigned issue to the implement bot — it never blocks an issue and never dedups against a PR-webhook it can't observe. An explicit per-ticket Bot/assignee always wins; the router only touches fully-unassigned issues. Implemented in pkg/dispatcher/loop.go (routeUnassignedIssue).
Hot-reload
The dispatcher watches iterion.dispatcher.yaml via fsnotify with a 200ms debounce. On a valid edit, the new config is swapped in:
| Field | Effect on edit |
|---|---|
polling.interval_ms | new tick cadence next loop |
agent.max_concurrent[_by_state] | applied next dispatch decision |
agent.running_state | applied next dispatch + revert |
agent.max_retry_backoff_ms | applied next retry calc |
hooks.* | applied next dispatch |
dispatch.vars | applied next dispatch |
workspace.persist | applied next dispatch; resumed runs preserve their original workspace shape |
stall.timeout_ms | applied next tick |
workflow:, tracker.kind:, workspace.root | warn-only; require restart |
tracker.* credentials | warn-only; require restart |
Invalid reloads (YAML errors, template parse errors, missing workflow file) keep the previous config and log a warning.
Tracker adapters
tracker.kind: native
The kanban store iterion ships with. Storage lives at <store-dir>/dispatcher/:
board.json                     # state + custom-field schema
issues/<id>.json               # one file per issue
events.jsonl                   # append-only audit log
See docs/native-tracker.md for the full reference.
tracker.kind: github
Shells out to the gh CLI. Auth uses the existing gh auth login by default; set tracker.github.token: $GITHUB_TOKEN for headless / CI.
tracker:
  kind: github
  github:
    repo: SocialGouv/iterion
    token: $GITHUB_TOKEN                # optional
    include_labels: [dispatcher-eligible]
    exclude_labels: [blocked, on-hold]
    claimed_label: iterion-claimed      # default
    state_mapping:
      ready:       { labels_include: [ready],   labels_exclude: [claimed] }
      in_progress: { labels_include: [claimed] }
The dispatcher's Claim adds iterion-claimed; Release removes it. gh issue edit --add-label refuses a label the repository does not carry, so the first claim creates the label when it is missing (gh label list then gh label create, once per dispatcher process, neutral grey — an existing label keeps the colour and description you gave it). A label deleted later is re-created on the next claim. The token therefore needs write access to the repository's labels (it already needs it for issues). ListCandidates filters via gh issue list --search so pagination and rate-limit handling come for free.
Environment hygiene. When tracker.github.token is set, iterion exports it as GH_TOKEN / GITHUB_TOKEN only to the gh subprocess, and restricts the inherited environment to a curated allowlist (PATH, HOME, locale, proxy, ssh-agent, gh and git config vars). This prevents unrelated secrets in iterion's environment (ANTHROPIC_API_KEY, OPENAI_API_KEY, FORGEJO_TOKEN, …) from leaking to gh's children via /proc/<pid>/environ. GH_TOKEN itself remains visible to gh's direct subprocesses (e.g. the git it shells out to for clone/push) — that is intrinsic to the env-based auth and only avoidable by writing the token into gh's on-disk credentials file via gh auth login --with-token. If your threat model includes co-located untrusted same-uid processes, prefer pre-authenticating gh interactively and leaving tracker.github.token empty.
Board mode — states from a Projects v2 board (ADR-097)
Add a project: block and the workflow state stops coming from labels: it is read from — and written to — the board's Status field, so a card a human dragged on the roadmap is a card the dispatcher sees, with no parallel label convention to maintain.
tracker:
  kind: github
  github:
    repo: SocialGouv/iterion
    token: $GITHUB_TOKEN                # REQUIRED in board mode
    claimed_label: iterion-claimed      # the claim is still a label
    project:
      owner: SocialGouv
      number: 203
      # owner_kind: org                 # or "user"; default org
      # candidate_statuses: [Planned]   # the columns eligible for dispatch
      # status_map:                     # override the shipped vocabulary
      #   Todo: ready
      #   Doing: in_progress
      #   Shipped: done
What changes, and what deliberately does not:
state_mappingis unused. The board column is the state; a second answer to the same question is how the two drift.ListCandidatesreturns the issues whose card sits in acandidate_statusescolumn (default[Planned], which the shipped map sends toready). Content still comes from the issue list — a project item carries no body, labels or assignee — soinclude_labels/exclude_labels/author_allowlistkeep applying.UpdateStatewrites theStatusfield. An issue the board does not carry yet is added to it: a dispatcher that could not record "In progress" because nobody had dragged the card on would leave the roadmap permanently behind.RefreshStatesreads the board once for the whole running set, instead of one REST call per issue.- The claim stays
claimed_label. A Projects v2 item carries no marker and no fencing epoch, so there is nothing to build a lease on — this adapter keeps decliningClaimLeaserexactly as it does in label mode, and the boot journal stays its only claim-recovery path. - A board it cannot read fails the poll, loudly. There is no fallback to label-derived states: dispatching on a state nobody configured is worse than not dispatching.
tokenis required. Board mode does not ridegh— Projects v2 is GraphQL, reached with a real API credential, andghauthenticates itself from its own config, which a cloud pod does not have. The token needs theprojectscope (classic PAT) or organization Projects: Read and write (fine-grained); a GitHub App needsorganization_projects: write.
A status a status_map does not cover is inert — the card is not a candidate and RefreshStates omits it — and a state with no column makes UpdateState return ErrTransitionRejected. The map must stay injective (two columns on one state is refused at construction, naming the collision): the reverse direction would otherwise be ambiguous.
See docs/github-board-sync.md for the board↔native card sync that pairs with this.
tracker.kind: forgejo
Direct REST client against the Forgejo (Gitea-compatible) API. Auth is Authorization: token $FORGEJO_TOKEN.
tracker:
  kind: forgejo
  forgejo:
    host: https://codeberg.org
    repo: owner/repo
    token: $FORGEJO_TOKEN
    include_labels: [ready]
    state_mapping:
      ready:       { labels_include: [ready] }
      in_progress: { labels_include: [claimed] }
Same label-driven semantics as GitHub. Claim adds the claimed label via POST /api/v1/repos/<owner>/<repo>/issues/<n>/labels (add-only); Release resolves the label's numeric id and DELETEs it by id. The bulk PUT .../labels replace endpoint is used only when the full label set is being rewritten.
tracker.kind: gitlab
Direct GitLab v4 REST client. Auth is a personal/project access token.
tracker:
  kind: gitlab
  gitlab:
    host: https://gitlab.com
    repo: group/project              # or a numeric project id
    token: $GITLAB_TOKEN
    include_labels: [ready]
    exclude_labels: [blocked]
    claimed_label: iterion-claimed   # required
    state_mapping:
      ready:       { labels_include: [ready] }
      in_progress: { labels_include: [claimed] }
Same label-driven claim/release semantics as the other forge trackers, mapped onto GitLab issues + labels.
HTTP / WS surface
The server.port setting starts the dispatcher's HTTP server (the same SPA the studio serves, so you get the kanban + dashboard at http://localhost:<port>). To run fully headless — no HTTP surface even when server.port is set — pass iterion dispatch --no-server.
| Endpoint | Method | Description |
|---|---|---|
/api/v1/dispatcher/state | GET | Live snapshot (running, retries, slots). |
/api/v1/dispatcher/refresh | POST | Force an immediate tick. |
/api/v1/dispatcher/reload | POST | Re-parse the YAML config. |
/api/v1/dispatcher/issues/{id} | GET | Per-issue dispatcher view. |
/api/v1/dispatcher/issues/{id}/cancel | POST | Cancel an in-flight run. |
/api/v1/dispatcher/ws | WS | Snapshot stream (push on each tick). |
/api/v1/native/* | — | Kanban store CRUD (when native is wired). |
/api/server/info | GET | SPA bootstrap (flags dispatcher_enabled, native_tracker_enabled). |
Single-instance safety
The dispatcher refuses to start a second instance against the same workspace root: it holds an exclusive flock on <workspace.root>/.dispatcher.lock for its lifetime.
For multiple dispatchers against the same tracker but different filesystems (e.g. dev laptop + CI), the per-issue claim marker (iterion-claimed label on GH/Forgejo, claim: field on native) prevents simultaneous dispatch — each dispatcher writes its own marker and refuses to dispatch issues marked by anyone else.
Claim lease + watchdog (native board, ADR-096)
On the native board (filesystem and Mongo), the claim is a fenced, leased token, not a bare marker. Each card carries claim_epoch (a per-issue fencing counter), claimed_at, and claim_lease_until; the owning dispatcher heartbeats the lease for the whole hold, and every write it makes while it holds the card is a compare-and-set on (claim, claim_epoch). A worker whose claim was stolen finds its late writes refused rather than clobbering the new owner.
The claim watchdog (ITERION_BOARD_CLAIM_REAPER=on, default off) runs every minute on each dispatcher and each cloud replica. It reclaims cards whose lease expired with nobody renewing — including cross-host dead owners, which the boot-time same-host pid-probe sweep never touched — by transferring the claim to a recovery owner (never freeing it first, which would let the next tick re-dispatch it), then routing the card by its recorded run's terminal state: finished → the completed column, terminal failure → the failed column, resumable → returned to the dispatch pool, paused → left alone (its retained claim is the parking brake, ADR-014). A running/queued run is never reclaimed, and any read error conserves. Roll it out in two releases: ship the lease fields + heartbeats first (reaper off), then enable the reaper once no pre-lease binary is left in the fleet.
The gate takes on/off, 1/0, true/false or yes/no (case-insensitive) — the spellings the repo's other ITERION_* toggles accept. Anything else leaves the watchdog OFF and is logged once at startup on both surfaces, so a mistyped cutover shows up in the log rather than as cards that quietly stay stuck.
The index net (native board, ITERION_NATIVE_INDEX_RESCAN). The native store keeps an in-memory index of issues/*.json, kept current by an inotify watch so a write another process makes (the iterion __mcp-board subprocess of a run) shows on /board and to the dispatcher at once. inotify is a lossy carrier: a host at fs.inotify.max_user_watches refuses the watch (ENOSPC), one at max_user_instances refuses the descriptor (EMFILE), a full kernel queue drops events (ErrEventOverflow), and a watched directory that is removed, renamed or unmounted loses its watch without a word (the loop asks fsnotify every 5 s whether the watch still exists, and hands over after two consecutive empty answers). Each of those used to leave the index frozen until the daemon restarted; each now falls back to a full rescan of issues/ — outside the store mutex, so board reads never wait behind disk I/O — every ITERION_NATIVE_INDEX_RESCAN (a Go duration or a bare number of seconds, default 2s; measured at ~4 ms for 200 cards and ~19 ms for 2 000). off, 0, 0s or any non-positive value disables the net and restores the blind-until-restart behaviour. Anything else — OFF, none, 2 s — is not a disable this recognises: it falls back to 2s rather than guess an operator out of their net, and the line the store writes when it arms one names the value it ignored. The symptom the net answers is a card written on disk that /board never shows; the log says which mode the store is in (native index watcher unavailable: … falling back to a 2s disk rescan, kernel event queue overflowed; index rebuilt from disk, inotify watch on issues/ lost mid-life). A card whose file is present but momentarily unreadable is kept as last seen, never dropped; a vanished issues/ directory is an error that leaves the index as it was, never an empty board.
The un-leased horizon (cloud board). A claim a mixed-fleet write stripped of its lease is only reclaimable once nothing has touched the card for ITERION_BOARD_UNLEASED_CLAIM_HORIZON (default 24h): an expired lease is positive evidence a heartbeat stopped, a missing one is an absence — and during a rolling deploy an OLD binary strips leases as it writes and does not heartbeat, so a short horizon would release a card its old-binary holder is still working. The default is sized for a day-long mixed window; a deployment whose rolling window is minutes can lower it (a Go duration, at least one claim lease — 15m — or the server refuses to start). Until the horizon elapses a stripped claim is unwritable by anybody (ADR-096 §6): that stuck window is the accepted cost of the mixed fleet, bounded by this dial.
Three properties of that routing are easy to assume wrongly:
- The card's state is read by the transfer, not by the listing. An operator can move a card between the two, and the watchdog honours what it finds — it will not overwrite a deliberate move into a column the card is not dispatched from. It does file a card still sitting in a launch column, because the move into the running column is best-effort on both launch paths: leaving it there would have the next tick launch a second run for work already delivered.
- A card in the running column with no run recorded is left alone. The run stamp is best-effort and lands after the launch, so its absence proves nothing — freeing the card could double-launch a live worker.
- A card whose recorded run is GONE is filed, never re-dispatched. A pointer at a run that
iterion runs pruneremoved (or that was deleted behind a tombstone) means a run happened and its outcome is unknowable. Freeing the card would mint a fresh run for work that may already be delivered, so the watchdog files it into the failed column with a give-up stamp naming the gone run and why (visible in the pipeline board's Needs attention lane, "The dispatcher gave up … recorded run … is gone"). Reopen or re-queue it to run it again; close it to acknowledge. The filing carries machine provenance, so no trigger fires on it. - Returning a card to the pool is bounded in cloud (
watchdogRunCeiling, 20 lifetime runs): the cloud launcher starts a fresh run rather than resuming the recorded one, so an always-failing card would otherwise be relaunched once per lease forever. The bound is a coarse SPEND backstop on the card's cumulative run count — every run it ever carried, whatever launched them — not a watchdog retry counter, so it must sit far above any healthy card's normal traffic. Past the ceiling a repark is filed as failed instead. The local dispatcher resumes the recorded run and needs no such bound.
Terminal board states (done, blocked) are sinks: the ordinary state-move family refuses to leave them (silent resurrection was any→any's worst case). The one sanctioned exit for a CARD is an operator reopen (the /board drag, iterion issue move, the pipeline Reset button); bots with board.move get the refusal with no fallback. A terminal→terminal move (closing a blocked give-up as done) stays an ordinary refiling.
Deleting a terminal column into a working one (DELETE /board/states/{name}?migrate_to=…) reopens every card in it at once. It is allowed — it is an explicit operator gesture on the board's own schema — but it is held to the same dependents check as a single-card reopen, so the column editor cannot become the way around a refusal.
Operational tips
- Always pair
iterion dispatchwithiterion studio(or just visithttp://localhost:<server.port>) — the dashboard is much more useful than tailing logs when debugging stall / retry behaviour. - For headless / containerized deployments, set
server.port: 0and scrape/api/v1/dispatcher/statevia Prometheus'json_exporteror similar. - Hot-reload is your friend during workflow iteration: tweak
dispatch.vars, save, watch the next dispatch pick up the new prompt without restarting the daemon. - The dispatcher does auto-transition on success. If the workflow left the card in
running_state, the dispatcher moves it toagent.completed_state(defaultreview). This is load-bearing, not a convenience:running_stateiseligible: trueon the default board so a crash can be recovered, and without the transition a workflow that never moves the card would be re-picked on every poll and burn model spend indefinitely. A workflow that moves the state itself (iterion issue move <id> --to done, or a board-capable bot) is left alone. Opt out withcompleted_state: none.
Deferred to v2
- Linear adapter.
- SSH workers (run dispatched workflows on remote hosts).
- Persistent retry queue (restart survives in-flight backoff timers).
- Multi-turn continuation (Symphony's single-thread agent loop).
- Cross-tracker fan-in (one dispatcher watching GitHub + Linear at once).
- Bi-directional sync (mirror GitHub → native, work locally, push back).